LM: Difference between revisions
Jump to navigation
Jump to search
| (51 intermediate revisions by the same user not shown) | |||
| Line 2: | Line 2: | ||
{| class="wikitable" | {| class="wikitable" | ||
! 🤖 Agent || 🧠 Model || 🚀 Engine || ⚙️ GPU & Driver || Evaluation | ! 🤖 Agent || 🧠 Model || 🚀 Engine || ⚙️ GPU & Driver || 📊 Evaluation | ||
|- | |- | ||
| style="width:200px;vertical-align:top" | | | style="width:200px;vertical-align:top" | | ||
| Line 8: | Line 8: | ||
: [[LM/jrswab_axe|axe]] | : [[LM/jrswab_axe|axe]] | ||
: [[LM/MCP|MCP]] | : [[LM/MCP|MCP]] | ||
| style="width:200px;vertical-align:top" | | | style="width:200px;vertical-align:top" | | ||
: [[LM/hf|hf (Model Management)]] | : [[LM/hf|hf (Model Management)]] | ||
: [[LM/Flint|Flint]] | |||
: [[LM/Qwen 3.8 27B|Qwen 3.8 27B]] | : [[LM/Qwen 3.8 27B|Qwen 3.8 27B]] | ||
: [[LM/Gemma 4|Gemma 4]] | : [[LM/Gemma 4|Gemma 4]] | ||
: [[LM/Bonsai 2 27B|Bonsai 2 27B]] | |||
: [[LM/Ornith 1.5 35B A3B|Ornith 1.5 35B A3B]] | |||
: [[LM/Experience|Experience]] | : [[LM/Experience|Experience]] | ||
| style="width:200px;vertical-align:top" | | | style="width:200px;vertical-align:top" | | ||
: [[LM/vLLM|vLLM]] | |||
: [[LM/llama-swap|llama-swap]] | : [[LM/llama-swap|llama-swap]] | ||
: [[LM/ | : [[LM/ComfyUI|ComfyUI]] | ||
: [[LM/llama.cpp for SYCL|llama.cpp for SYCL]] | : [[LM/llama.cpp for SYCL|llama.cpp for SYCL]] | ||
: [[LM/llama.cpp for | : [[LM/llama.cpp for CUDA|llama.cpp for CUDA]] | ||
: [[LM/SGLang|SGLang]] | : [[LM/SGLang|SGLang]] | ||
: [[LM/Inference Engine Comparison|Comparison]] | |||
| style="width:200px;vertical-align:top" | | | style="width:200px;vertical-align:top" | | ||
: Intel Arc Pro B70 | : Intel Arc Pro B70 | ||
| Line 37: | Line 31: | ||
:: [[LM/.bashrc for B70|.bashrc for B70]] | :: [[LM/.bashrc for B70|.bashrc for B70]] | ||
:: [[LM/Intel Pro Arc B70|Experiment]] | :: [[LM/Intel Pro Arc B70|Experiment]] | ||
: NVIDIA RTX 3060 | |||
:: [[LM/Install NVIDIA driver|Install driver]] | |||
: AMD Ryzen AI 7 350 | : AMD Ryzen AI 7 350 | ||
:: [[LM/Ryzen AI 7 350|Experiment]] | :: [[LM/Ryzen AI 7 350|Experiment]] | ||
: Tools | : Tools | ||
:: [[LM/Install nvtop|Install nvtop]] | :: [[LM/Install nvtop|Install nvtop]] | ||
:: [[LM/PCIe Trouble Shooting|PCIe Trouble Shooting]] | |||
: Comparison | |||
:: [[LM/GPU Comparison]] | |||
| style="width:200px;vertical-align:top" | | | style="width:200px;vertical-align:top" | | ||
: [[LM/Performance|Performance]] | : [[LM/Performance|Performance]] | ||
|} | |} | ||
| Line 52: | Line 49: | ||
* [https://storage.openvinotoolkit.org/repositories/openvino/packages/2026.3/linux/ OpenVINO 2026.3 supports Ubuntu 26] - 2026-08-04 | * [https://storage.openvinotoolkit.org/repositories/openvino/packages/2026.3/linux/ OpenVINO 2026.3 supports Ubuntu 26] - 2026-08-04 | ||
= | = Models management = | ||
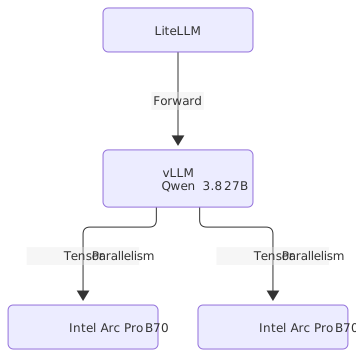
<quickmmd name="models-handling-infra"> | |||
flowchart TD | |||
A(LiteLLM) | |||
B(vLLM<br>Qwen 3.8 27B) | |||
C1(Intel Arc Pro B70) | |||
C2(Intel Arc Pro B70) | |||
A --> |Forward| B | |||
B --> |Tensor Parallelism| C1 & C2 | |||
%% C1 --- |XCCL| C2 | |||
</quickmmd> | |||
* llama-swap can launch model, cannot manage users. | |||
* LiteLLM cannot launch model, can manage users. | |||
= Investigating vLLM on Intel Arc Pro B70 = | |||
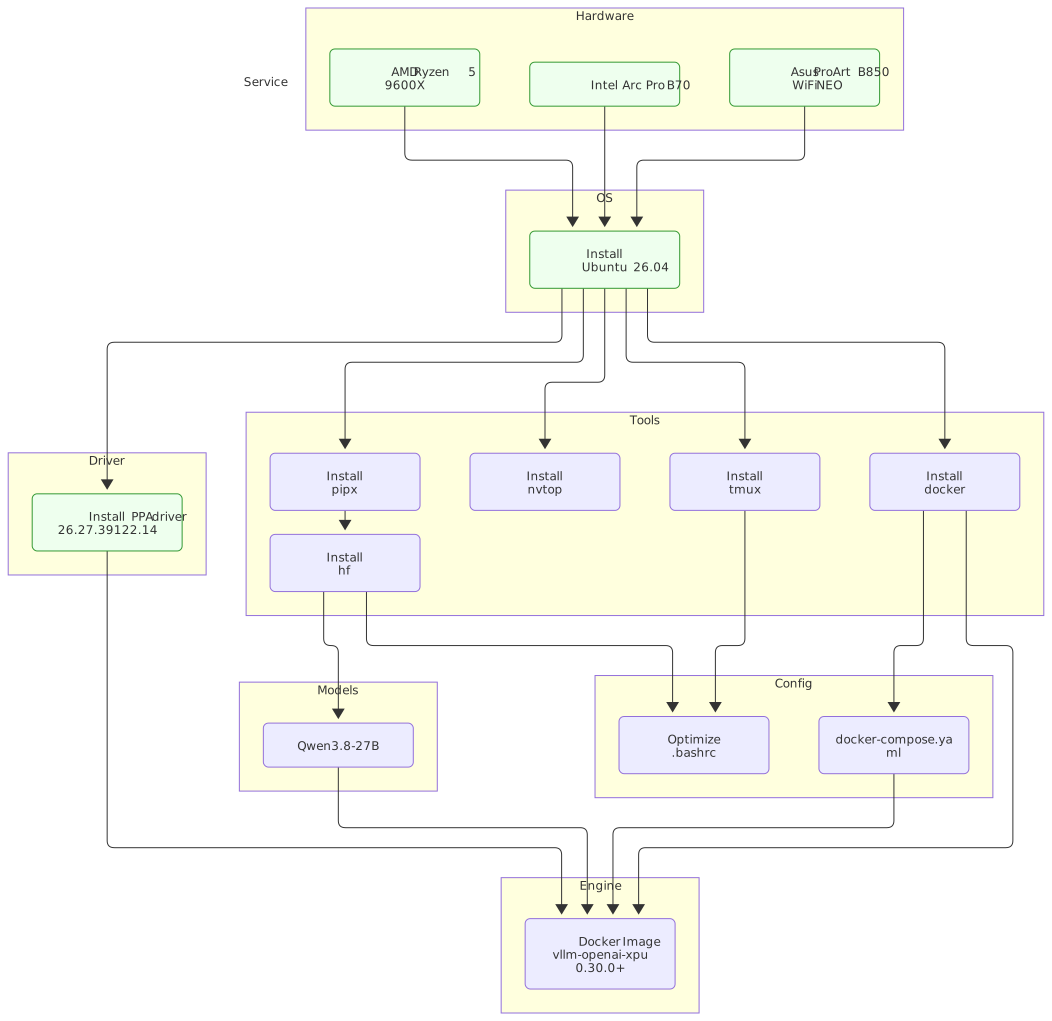
<quickmmd name="tinkering-b70-vllm"> | |||
flowchart TD | |||
subgraph Hardware | |||
A1(Intel Arc Pro B70):::node-okay | |||
A2(Asus ProArt B850 WiFi NEO):::node-okay | |||
A3(AMD Ryzen 5 9600X):::node-okay | |||
end | |||
subgraph OS | |||
B1(Install<br>Ubuntu 26.04):::node-okay | |||
A1 & A2 & A3 --> B1 | |||
end | |||
subgraph Driver | |||
C1(Install PPA driver<br>26.27.39122.14):::node-okay | |||
B1 --> C1 | |||
end | |||
subgraph Tools | |||
T1(Install<br>pipx) | |||
T2(Install<br>hf) | |||
T3(Install<br>nvtop) | |||
T4(Install<br>tmux) | |||
T5(Install<br>docker) | |||
T1 --> T2 | |||
B1 --> T1 | |||
B1 --> T3 | |||
B1 --> T4 | |||
B1 --> T5 | |||
end | |||
subgraph Models | |||
M1(Qwen3.8-27B) | |||
T2 --> M1 | |||
end | |||
subgraph Config | |||
V1(Optimize<br>.bashrc) | |||
V2(docker-compose.yaml) | |||
T2 --> V1 | |||
T4 ----> V1 | |||
T5 --> V2 | |||
end | |||
subgraph Engine | |||
E1(Docker Image<br>vllm-openai-xpu<br>0.30.0+) | |||
C1 --> E1 | |||
T5 --> E1 | |||
M1 --> E1 | |||
V2 --> E1 | |||
end | |||
subgraph Service | |||
end | |||
classDef node-okay fill:#efe,stroke:#393 | |||
classDef node-warn fill:#fff0e0,stroke:#d63 | |||
classDef node-fail fill:#fee,stroke:#d33 | |||
classDef node-todo fill:#eee,stroke:#777 | |||
</quickmmd> | |||
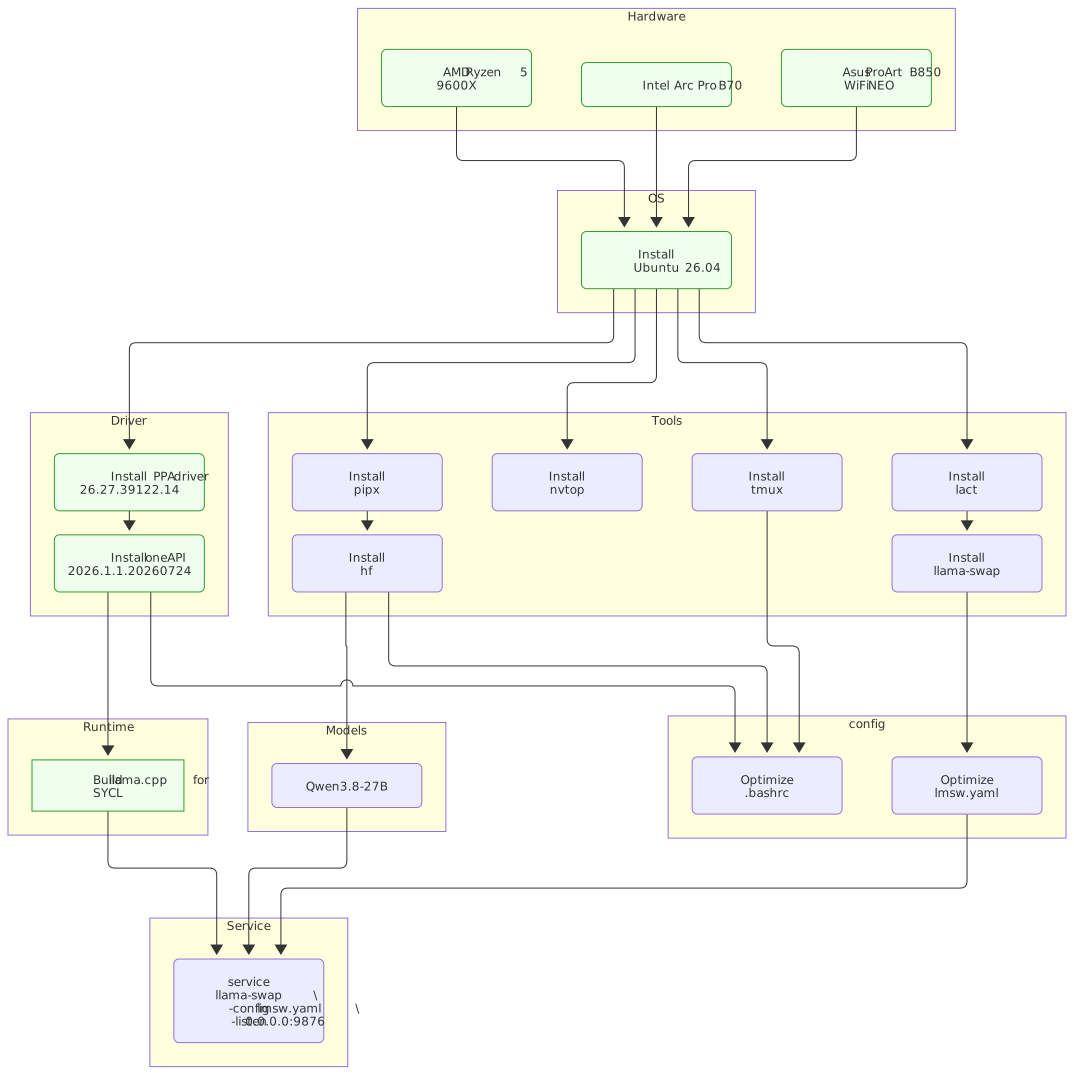
= Investigating llama.cpp on Intel Arc Pro B70 = | |||
<quickmmd name="tinkering-b70"> | <quickmmd name="tinkering-b70"> | ||
| Line 70: | Line 147: | ||
C1(Install PPA driver<br>26.27.39122.14):::node-okay | C1(Install PPA driver<br>26.27.39122.14):::node-okay | ||
C2(Install oneAPI<br>2026.1.1.20260724):::node-okay | C2(Install oneAPI<br>2026.1.1.20260724):::node-okay | ||
C1 --> C2 | |||
C1 --> C2 | |||
B1 --> C1 | B1 --> C1 | ||
end | end | ||
| Line 77: | Line 153: | ||
subgraph Runtime | subgraph Runtime | ||
D1[Build llama.cpp for<br>SYCL]:::node-okay | D1[Build llama.cpp for<br>SYCL]:::node-okay | ||
C2 --> D1 | C2 --> D1 | ||
end | end | ||
| Line 103: | Line 173: | ||
subgraph Models | subgraph Models | ||
M1(Qwen3.8-27B) | M1(Qwen3.8-27B) | ||
T2 --> M1 | |||
T2 --> M1 | |||
end | end | ||
| Line 111: | Line 180: | ||
V2(Optimize<br>lmsw.yaml) | V2(Optimize<br>lmsw.yaml) | ||
C2 --> V1 | C2 --> V1 | ||
T2 --> V1 | T2 --> V1 | ||
T4 ---> V1 | T4 ----> V1 | ||
T6 ---> V2 | T6 ---> V2 | ||
end | end | ||
Latest revision as of 01:58, 26 October 2026
Topics
| 🤖 Agent | 🧠 Model | 🚀 Engine | ⚙️ GPU & Driver | 📊 Evaluation |
|---|---|---|---|---|
|
News
Models management
- llama-swap can launch model, cannot manage users.
- LiteLLM cannot launch model, can manage users.
Investigating vLLM on Intel Arc Pro B70
Investigating llama.cpp on Intel Arc Pro B70